Documentation / THOR Data
12 / 22
The first task
Launch begins with frame-level action captioning on first-person video.
Contributors identify the action visible in a short approved clip, mark when it begins and ends, and merge adjacent frames that show the same action. The result is a clean sequence of labelled behaviour through time.
Input / egocentric video clip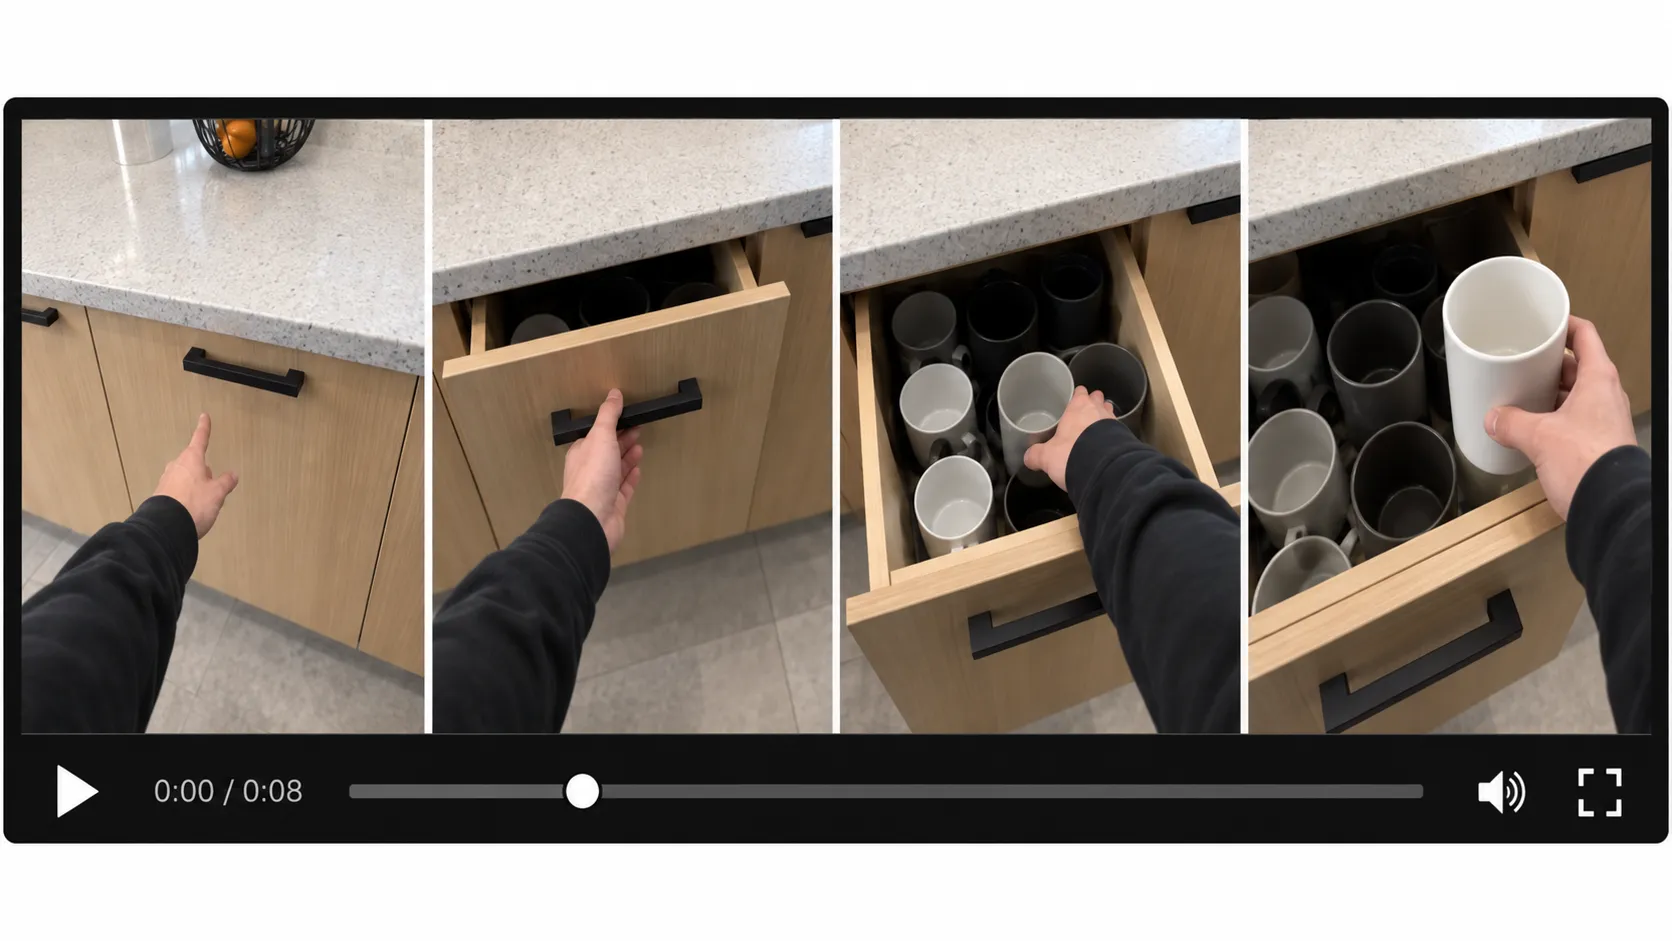
0s8s
Output / merged segments
- 0.0–2.0 secReach for drawer
- 2.0–4.6 secOpen drawer
- 4.6–8.0 secRemove cup
One short action phrase is assigned per frame. Identical adjacent labels merge into one continuous segment.
One clip becomes a time-aligned action record
The scope is narrow enough for clear rules and useful enough for video-language and robot-learning datasets. It lets THOR test publication, production, scoring and acceptance with output that a buyer can inspect.